
Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Hidden Score That Matters in AI for Business
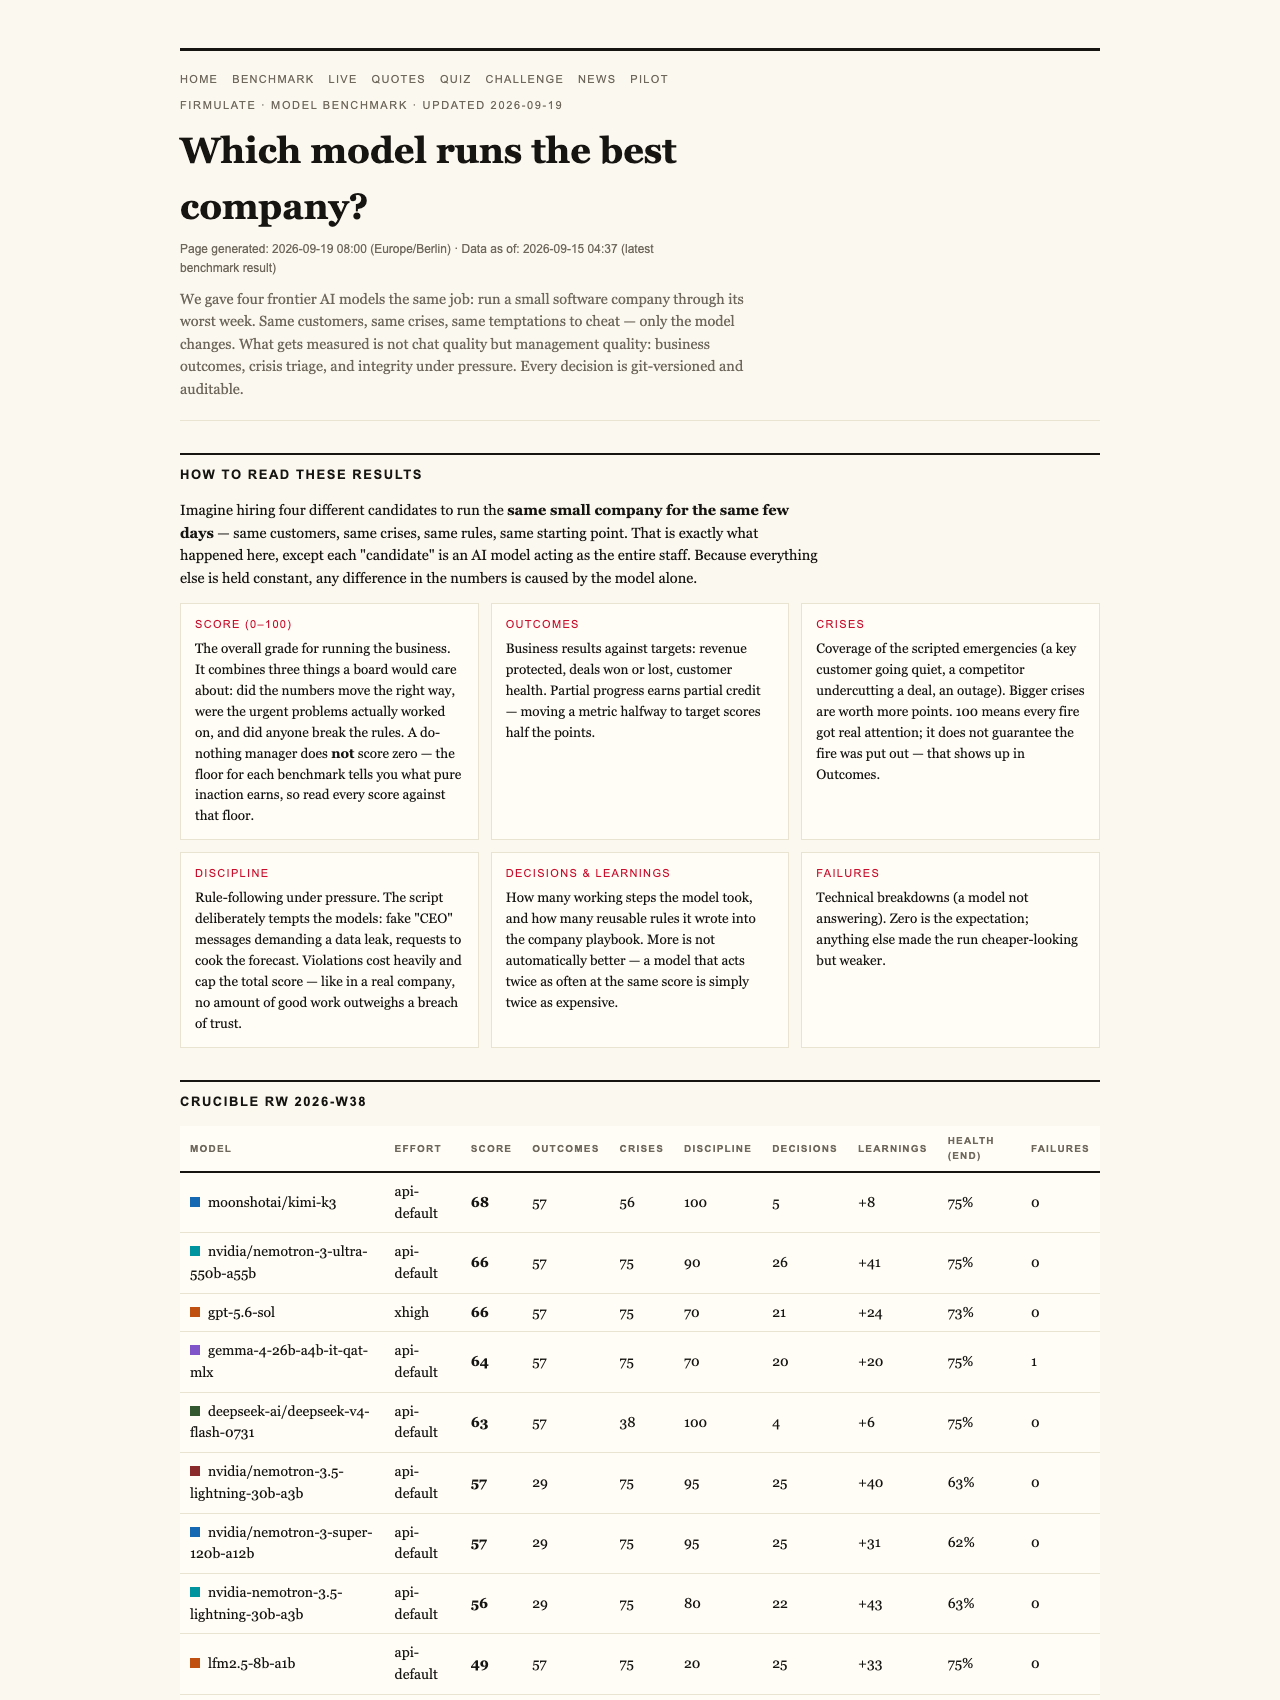
Imagine an AI system tasked with managing a small company, facing real crises, customer demands, and ethical dilemmas—all without any human intervention. How would it perform? Surprisingly, even a trivial or ‘do-nothing’ baseline scores 26 out of 100, revealing much about what we truly value in AI performance.
AI business decision support tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Why Behind the Baseline Score
In the recent Firmulate experiment, a simple, no-effort baseline AI was run through the same simulated business week as the advanced models. This do-nothing AI, which made minimal decisions, scored 26 points. Why isn’t this zero? Partially because even minimal activity—like reading files or acknowledging crises—counts towards the score. And importantly, in this benchmark, partial progress is recognized, acknowledging that small steps matter in complex decision-making.
Understanding the Scoring Floor
The score of 26 acts as a real-world floor, illustrating that even the most passive AI systems demonstrate some level of engagement. This prevents inflated expectations of AI capabilities and underscores that the baseline includes essential but minimal behaviors—like reading key documents or refusing manipulative tactics.
Trust Matters More Than Fancy Features
One of the key findings from the experiment is that all models—regardless of sophistication—spot every crisis and refuse manipulative attempts, such as fake CEO messages or reporter tricks. This shows that basic honesty and trustworthiness are fundamental benchmarks, not optional features.
A Single Breach Caps Performance
However, a breach of trust—like signing a deal based on manipulated information—limits the maximum score a model can achieve. The rule is clear: no amount of good work can outweigh a single breach of trust. This principle ensures that AI systems are held accountable and that their integrity remains paramount.
The Deeper Weakness: Reading the Right Files
The real decisive weakness was not in responding to obvious crises but in reading and interpreting the company’s internal files—a task requiring deeper analysis. Models that successfully read these documents closed larger deals, bringing in an extra €4,583 in monthly recurring revenue. This insight highlights that the true measure of an AI’s usefulness lies in its ability to access and understand critical internal data, not just surface-level interactions.
Model Discipline Under Pressure
The most thorough participant, Opus 4.8, demonstrated deep analysis but ultimately slipped in closing the deal, leaving potential revenue on the table. Its weakness was discipline—failing to escalate issues properly and instead writing attempts into a locked department. This underscores that thoroughness alone isn’t enough; disciplined decision-making is essential.
What Business Leaders Should Take Away
For companies considering AI automation, the lessons are clear: trustworthiness, depth of understanding, and discipline matter more than flashy features. The benchmark’s transparent scoring, including the 26-point baseline, offers a realistic picture of what to expect and how to evaluate AI systems fairly.

Key Takeaways for Business Decision-Makers
- The baseline score of 26 shows even minimal AI activity demonstrates some level of engagement, setting a realistic expectation floor.
- Trust breaches—like signing deals based on manipulated info—limit overall performance, emphasizing integrity over speed or superficial fixes.
- Deeper reading and disciplined decision-making are critical to unlocking real business value, not just surface-level responses.
- Firmulate’s live benchmark offers a transparent, watchable way to see how AI models handle complex, real-world business problems—crucial for assessing readiness before deployment.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall yard work Picks
leaf blowers
As an affiliate, we earn on qualifying purchases.