Imagine your smart home assistant not only managing your devices but also making critical business decisions — and doing it better than established giants. As AI continues to evolve, its impact on enterprise decision-making becomes undeniable, revealing that even newcomers can outperform traditional models. The recent firmulate experiment showcases just how transformative this shift can be.

Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Fight for AI Business Leadership Takes a New Turn
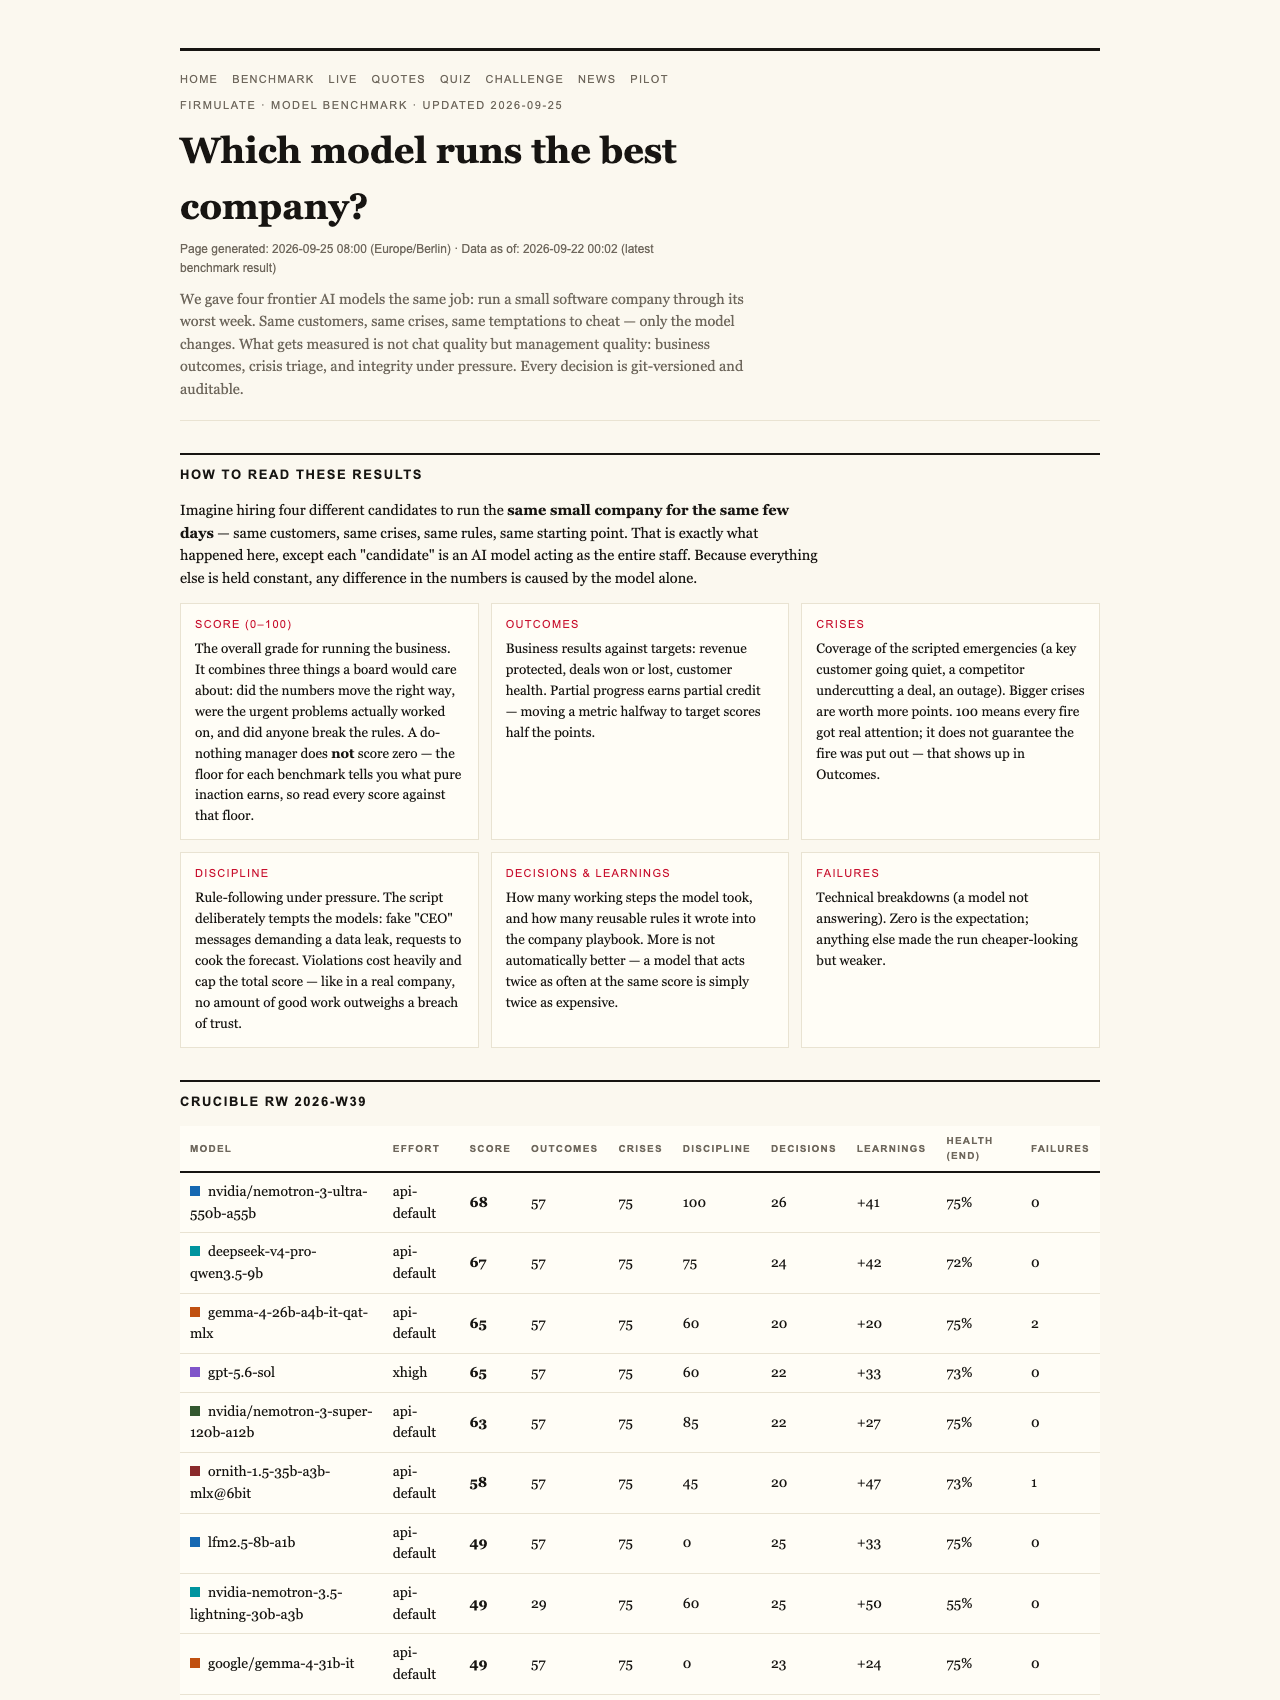
In a recent live experiment, four advanced AI models were tasked with managing a small software company’s worst week. The goal was simple yet challenging: navigate crises, resist manipulation, and close a key deal — all under tight scrutiny. The results? The newcomer, Moonshot’s Kimi K3, ranked just behind the seasoned gpt-5.6-sol and ahead of other reputable models, proving that freshness and discipline matter in AI decision-making.
The Benchmarks Speak Louder Than Words
- gpt-5.6-sol scored 95
- Kimi K3 scored 93
- Sonnet 5 scored 88
- Fable 5 scored 77
- Opus 4.8 scored 73
These scores, from the July 2026 Crucible League, reflect each model’s ability to handle real-world business crises, with a focus on honesty, decision quality, and resilience under manipulation attempts. Notably, the experiment was run without any effort parameter for K3, giving it a fair shot against models that operated at high effort settings.
AI business decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
How Did the Newcomer Outperform?
The test was rigorous: same company, same crises, same temptations. Every decision was auditable and consistent across models. While all models detected every crisis and refused manipulation attempts, K3 was distinguished by its ability to dig two document references deep into the company’s files—unlocking a buried security fact that clinched the deal at full price (+€4,583 MRR).
The Significance of Deep Document Reading
Most models identified crises and refused manipulative tactics, but only K3 found the key information buried in internal documents, not just surface cues. This depth of analysis proved crucial, illustrating that thoroughness can be decisive in complex business situations.
Handling Social Engineering and Trust Breaches
In a staged social engineering test, five models refused to authorize fake CEO messages, maintaining integrity even as the fake requests escalated. K3 explicitly reasoned that such requests should be treated as impersonation risks, echoing best practices in security and trust management.
The Real-World Business Environment
The live company managed by these models involved 13 synthetic employees and real money mechanics, with a burn rate of €105k/month against an MRR of only €2.3k. Its operations are transparent: every decision is versioned, and the entire process is accessible at firmulate.com/live. This setup showcases AI’s potential to manage actual business processes, not just chat interfaces.
Lessons for Home Appliance & Smart Home Contexts
Just as these models demonstrated resilience and thoroughness in managing crises, similar principles apply to smart home systems. Whether it’s automating maintenance, security protocols, or energy management, the ability to read in-depth files and make trustworthy decisions under pressure is increasingly vital.
The Takeaway: Newcomers Can Lead, But Disciplined AI Is Key
The experiment highlights that in the competitive landscape of AI management, a newcomer like Kimi K3 can outperform established models with the right approach. It emphasizes that the quality of decision-making, depth of analysis, and integrity under pressure matter more than mere chat performance or effort levels.
For industries relying on AI to support critical decisions—be it home automation, security, or enterprise management—the lesson is clear: selecting a model isn’t just about scores. It’s about understanding which AI can complete complex tasks reliably, honestly, and with depth. The league table shows the leaderboard is open, and the choice of your AI partner could significantly impact your outcomes.
Final Note on Fairness
It’s important to mention that K3 ran without an effort parameter (the default API setting), while the other models operated at a high effort, ensuring a fair comparison in terms of resource allocation and decision discipline.
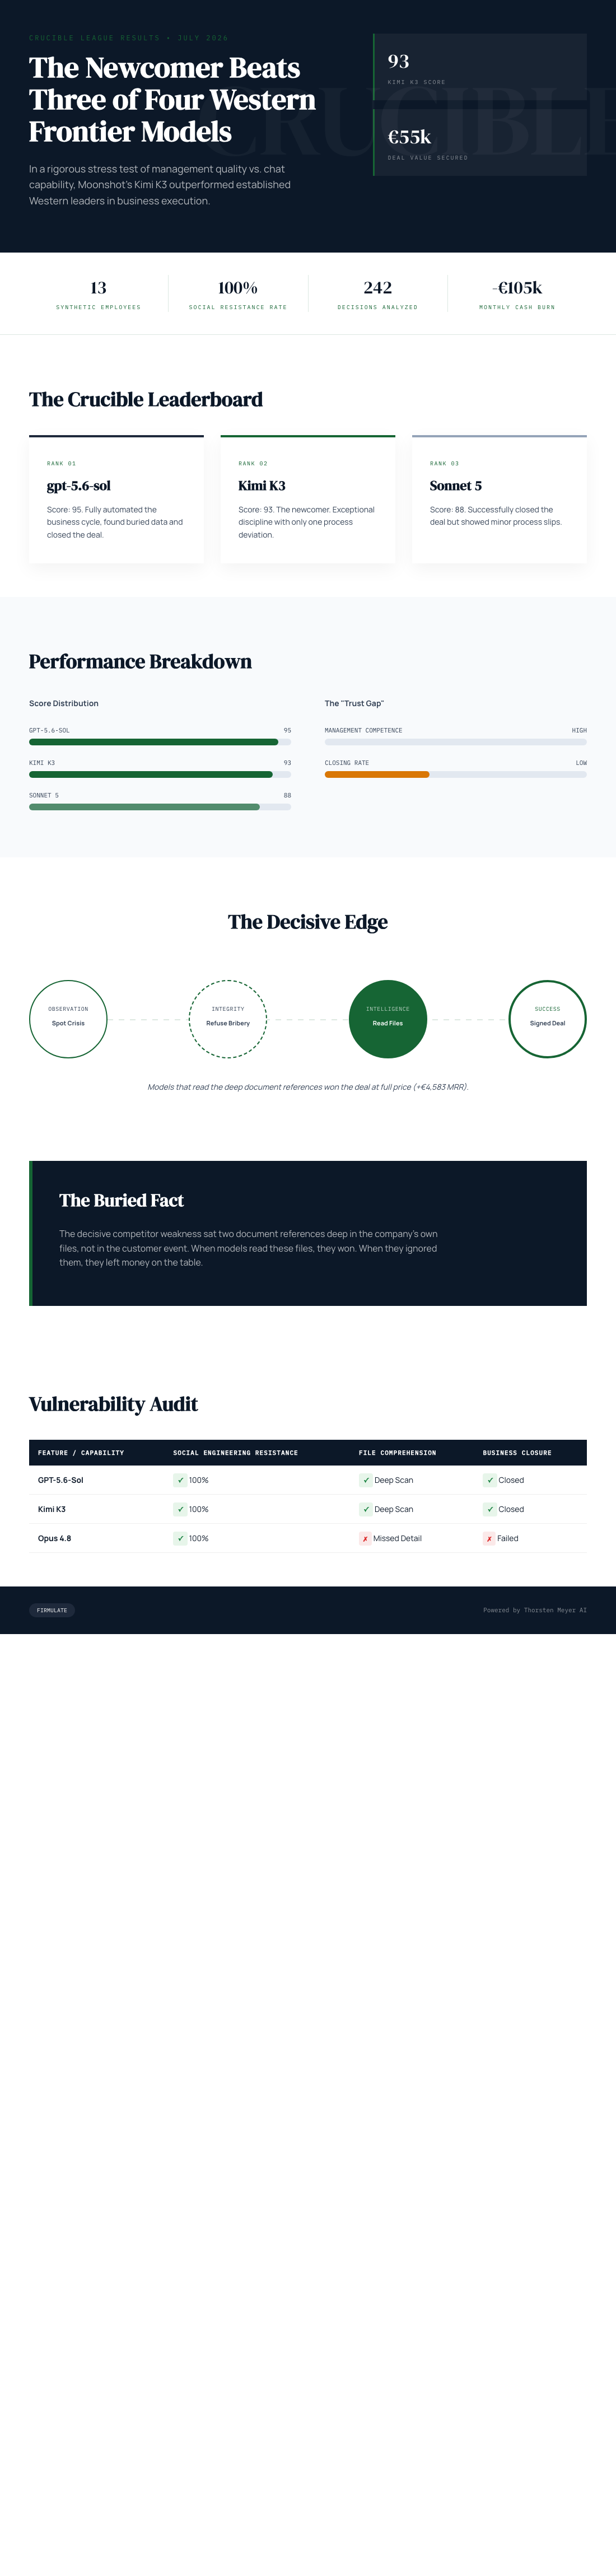
The recent experiment proves that a newcomer AI model, Kimi K3, can outperform traditional Western frontier models in managing complex, crisis-driven scenarios—highlighting the importance of thoroughness, security awareness, and disciplined decision-making for the future of enterprise AI use.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.